GLM-5.2
GLM-5.2 is the flagship model built for the long-task era, featuring a truly usable 1M context window and 128K max output tokens. With GLM-5.2, developers can complete the entire development chain from requirements to deployable artifacts in a single continuous task. GLM-5.2 keeps engineering standards reliable across extended sessions.
Feedback
freeTrialImage.bannerPity
freeTrialImage.upgradeUnlock
- ✓freeTrialImage.benefitHd
- ✓freeTrialImage.benefitWatermark
- ✓freeTrialImage.benefitUnlimited
All Tools
Discover our comprehensive AI-powered animation toolkit
MiniMax H3
MiniMax H3 AI Video Generator
Seedance 2.5
The Future of AI Video Is Here.
Seedance 2.0
The Future of AI Video Is Here.

Veo3.1
Create Stunning Videos with Veo3.1
FLUX 3 Video Generator
Kling 3.0
Next-Gen AI Video Generator
Grok Video Generator
Create Videos from Text or Images with AI
MiniMax H3 video generator
MiniMax H3 AI Video Generator
What Makes GLM-5.2 Stand Out
GLM-5.2 is a flagship base model designed for work that runs long, pairing a solid 1M lossless context with 128K max output tokens. Its coding-agent behaviour has been sharpened for large-scale implementation, automated research and performance tuning. Across extended sessions, GLM-5.2 holds engineering standards steady and keeps an entire project-level context inside a single reasoning chain.
- A Truly Usable 1M ContextGLM-5.2 keeps a full 1M-token window in play, enough for project-wide engineering and tasks that run for hours without losing the thread.
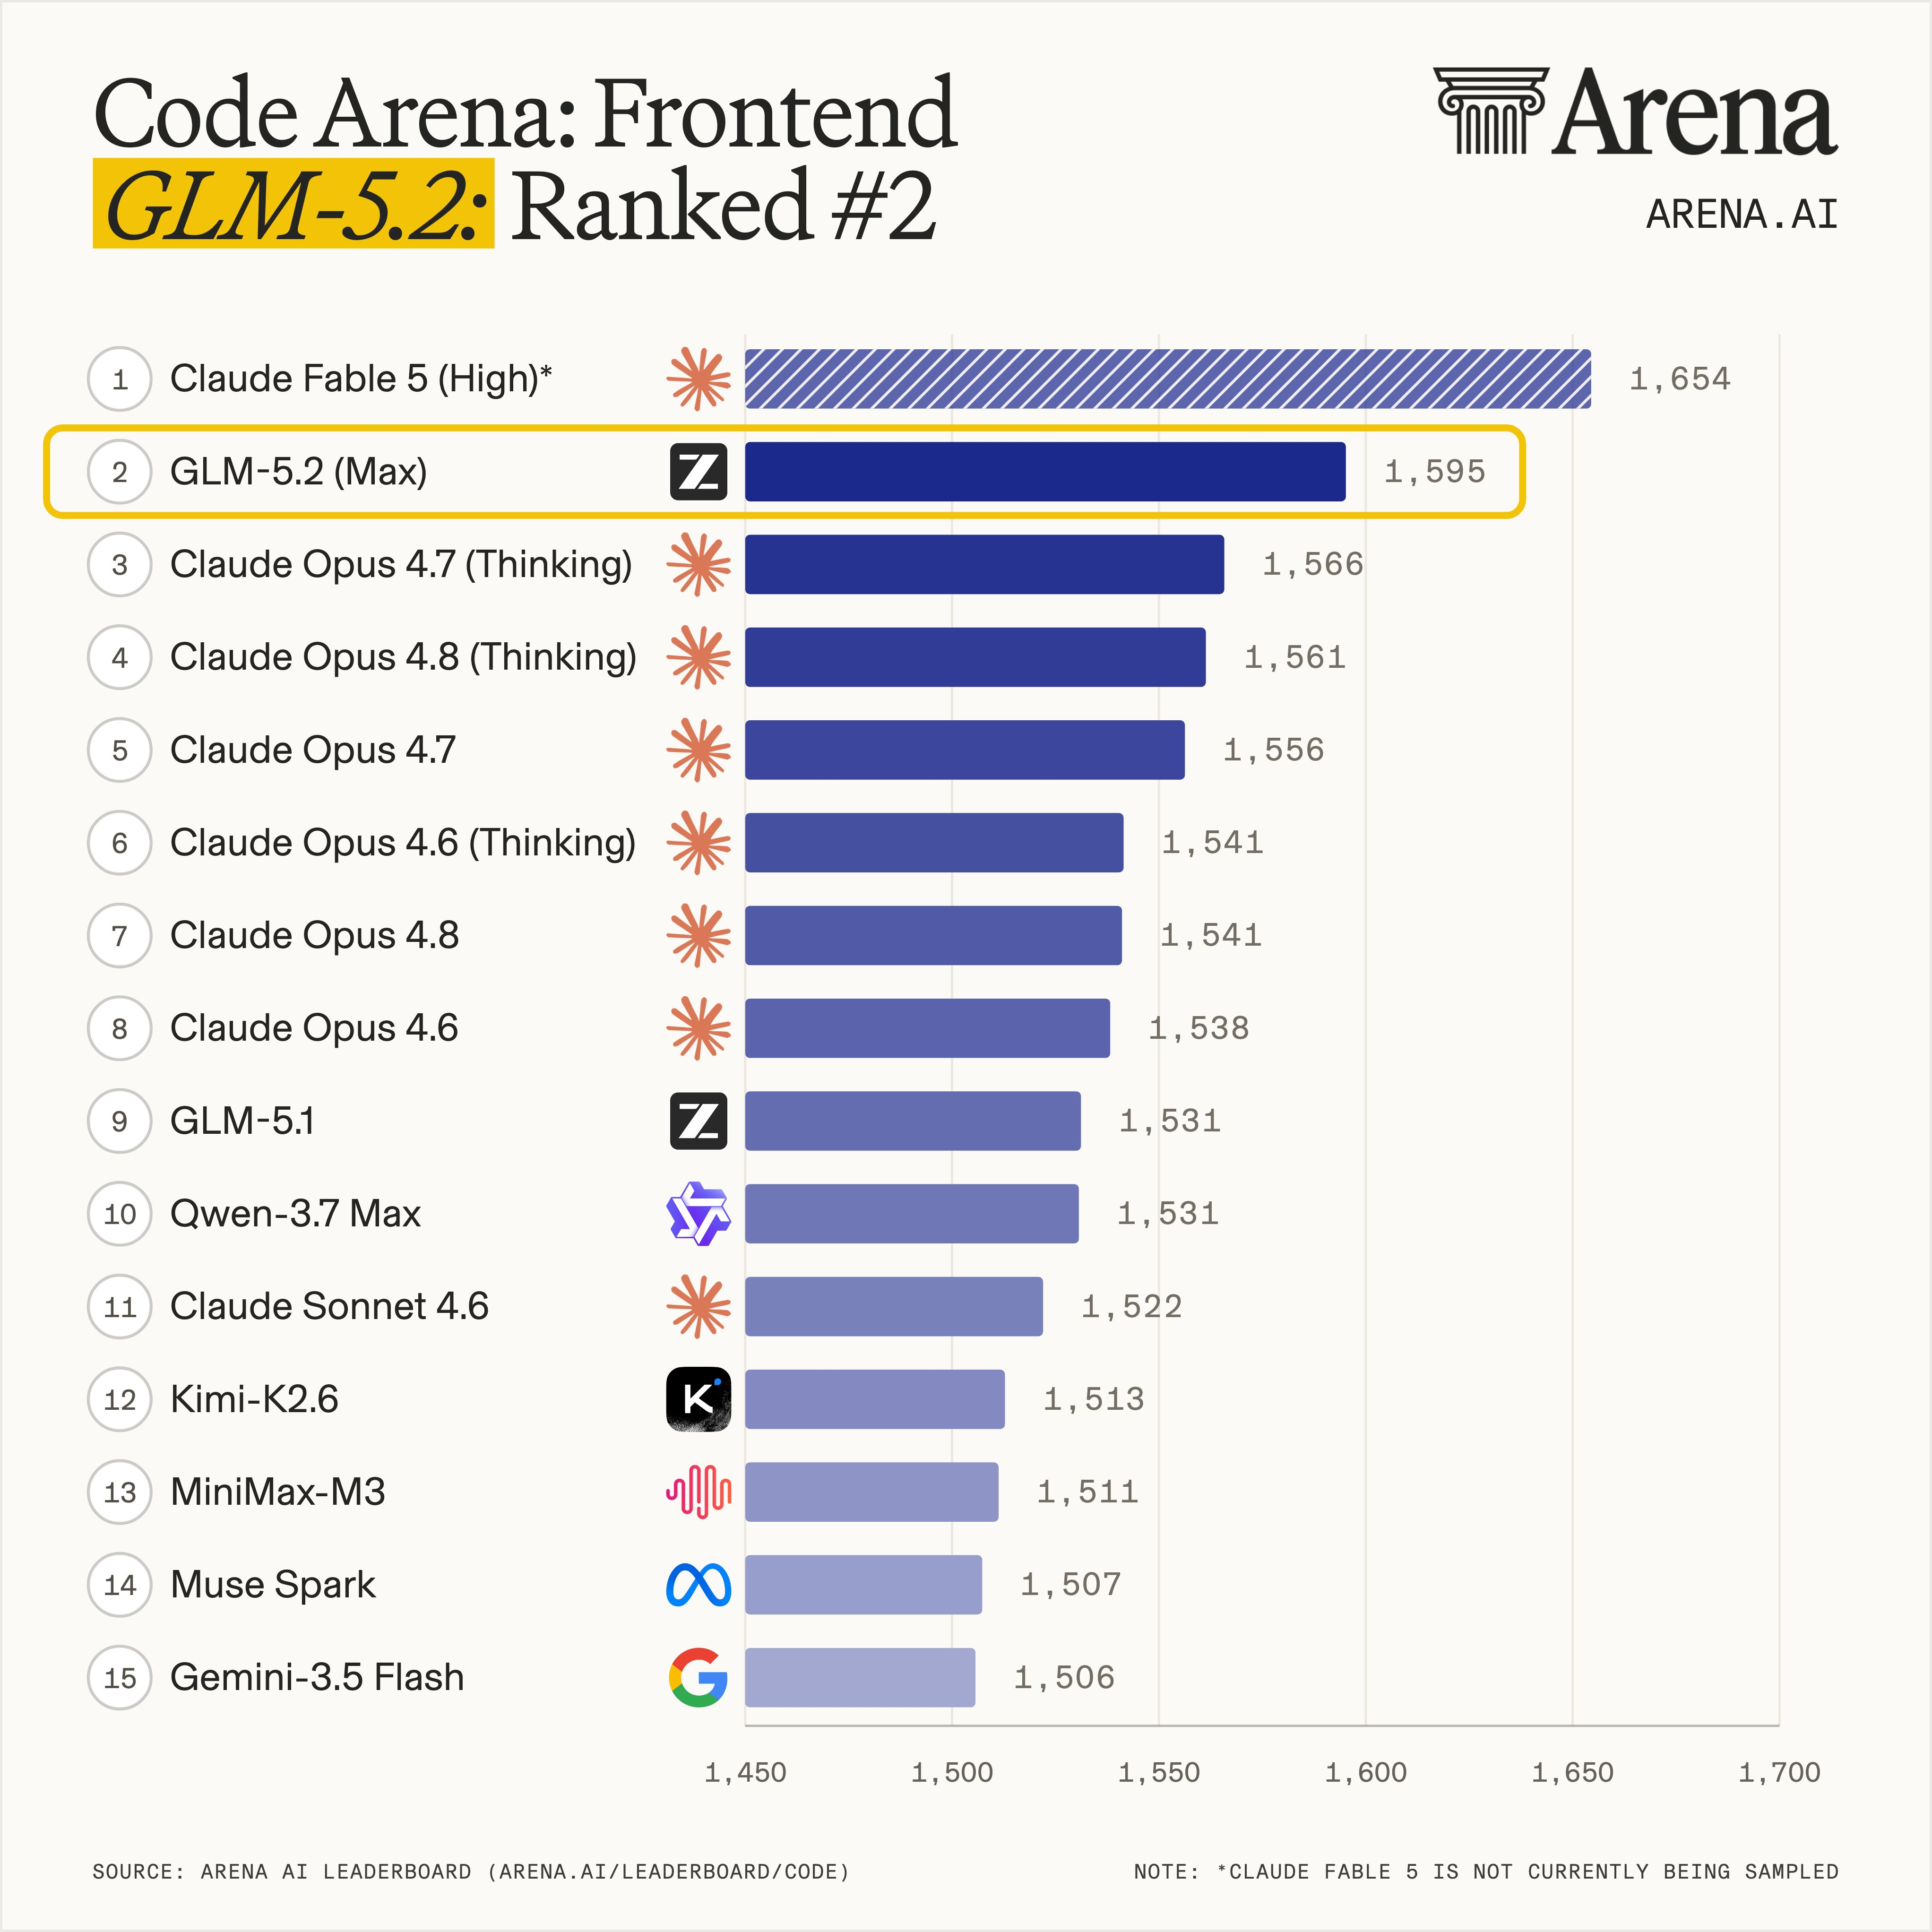
- Best-in-Class CodingGLM-5.2 holds open-source SOTA on mainstream coding benchmarks and sits first globally on Code Arena among currently available models.
- Production-Grade DisciplineCode style, architectural boundaries and dependency constraints are respected by GLM-5.2 as if a senior reviewer were watching every commit.
Three Steps to Start with GLM-5.2
Connect, describe and ship — GLM-5.2 slots into your development and video creation work in three simple moves.
What GLM-5.2 Can Do
GLM-5.2 ships with several thinking modes, live streaming, tool calling, context caching, structured output and MCP support — everything a full development workflow needs.
Multiple Thinking Modes
Switch between reasoning depths in GLM-5.2 to match anything from a quick fix to a deeply complex task.
Live Streaming Replies
GLM-5.2 streams tokens as they are produced, so interactive interfaces feel responsive rather than stalled.
Tool and Function Calling
GLM-5.2 connects to external services and tools through robust function calling, extending what one session can accomplish.
Smart Context Caching
GLM-5.2 caches what it has already read, cutting latency and cost on long, multi-turn conversations.
Structured Output
Ask GLM-5.2 for JSON or other structured formats and pipe the results straight into your own systems.
MCP Connectivity
GLM-5.2 reaches out to MCP tools and data sources on demand, opening new workflows for your application.
GLM-5.2: Frequently Asked Questions
The questions readers ask most about GLM-5.2 — from context limits and speed to coding benchmarks and supported projects.
What exactly is GLM-5.2?
GLM-5.2 is a flagship base model made for long-running work, offering a genuinely usable 1M-token context and up to 128K output tokens for project-level engineering.
Which tasks can GLM-5.2 handle?
GLM-5.2 covers project-level engineering, long-range refactoring, real-device mobile debugging, mini-program and mini-game builds, and research replication.
How quickly does GLM-5.2 respond?
GLM-5.2 works through long tasks efficiently, using streaming output and context caching to keep performance steady across extended sessions.
Is GLM-5.2 strong at coding?
Yes. GLM-5.2 holds open-source SOTA on mainstream coding benchmarks and ranks first globally on Code Arena among available models, putting it in the same conversation as Claude Opus 4.8.
How much context can GLM-5.2 hold?
GLM-5.2 offers a solid 1M lossless context window, so project-scale engineering context stays intact with stable performance throughout.
What kinds of projects suit GLM-5.2?
GLM-5.2 fits web development, mobile apps, WeChat mini-programs, mini-games, scientific code replication and coding-to-video workflows.
Put GLM-5.2 to Work Today
Start building with GLM-5.2 and see what a genuinely usable 1M-token context does for your development projects.